AI is stealing your time.
Your spec is still a prompt.
Every run, AI interprets it again — a different guess each time. Source shouldn't be prompt-guessed. Make it compiled.
interpreted every run
Subscriptions can be cancelled at any time.
Cancelled subscriptions stay active until the end of the current billing period.
Subscription
============
** id          : ID
*  owner       : Reference@Customer
*  status      : String
-  cancelledAt : Date

Cancellation Rules
??????????????????
@ input:: subscription: Subscription
@ output:: canCancel: Boolean

rule activeOnly
| when: subscription.status == "ACTIVE"
| then: canCancel = trueSource Code has a missing counterpart.
Meet the Source Model.
Code says HOW. The Source Model says WHAT.
Typed. Versioned. Validated. Compiled. Kept for the next change.
Today: structure, relationships, operations. Next: outcomes and constraints.
- WHY
- Intent
- The purpose.
- WHAT
- Source Model
- The domain, relationships, and behavior.
- HOW
- Source Code
- The implementation.
Subscription
============
** id          : ID
*  owner       : Reference@Customer
*  status      : String
-  cancelledAt : Date

Cancellation Rules
??????????????????
@ input:: subscription: Subscription
@ output:: canCancel: Boolean

rule activeOnly
| when: subscription.status == "ACTIVE"
| then: canCancel = true

rule notActive
| when: otherwise
| then: canCancel = false
One rule. One place. Readable and compilable.
Spec-driven dev has the right intent. And the wrong implementation.
It made the spec the source of truth. Then asked AI to guess the code.
- 01The spec is prose. Prose is ambiguous.
Natural language leaves the HOW open to interpretation. If implementation details are still debatable, the foundation is already weak.
- 02The AI is non-deterministic.
Same spec, same model, two runs: two codebases, two different bugs.
- 03The human is the bottleneck.
Every generated diff, reviewed line by line, by an exhausted senior at 4:47pm on a Friday.
Prose in. LLM guess out. Different every time.
Three flaws, compounding.
Spec-driven vs Model-Native.
Same goal. A better way for the AI-era.
- Interpreted.
- Regenerated.
- Re-reviewed.
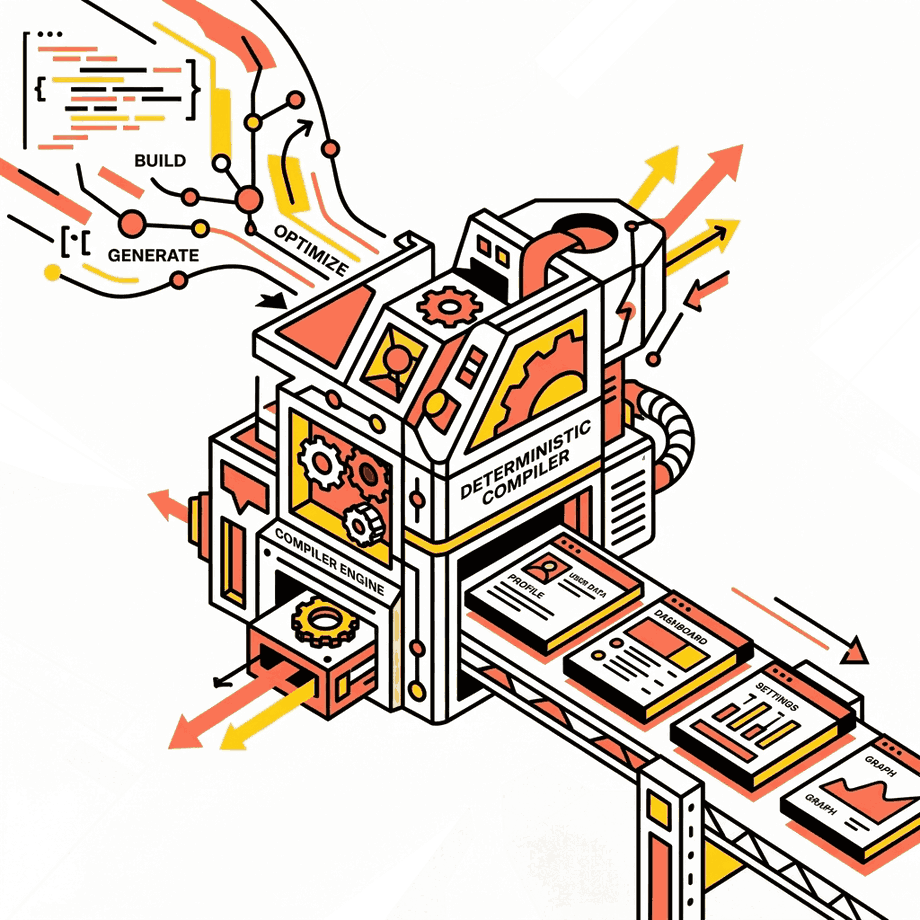
- Validated.
- Compiled.
- Reviewed once.
Stop treating the spec as instructions for AI. Start treating it as source.
Welcome to Model-Native Development.
ModelHike fixes all three — by moving up from source code to the Source Model.
-
fixes: ambiguity
Declaration, not prose.
Stop describing your app in English and hoping AI reads it right. Define entities, APIs, relationships, and rules precisely in one typed DSL.
-
fixes: drift
Compilation, not generation.
Same model + blueprint → same output. Auditable. Reproducible. Shippable.
-
fixes: the bottleneck
Review at the source.
Review a few lines of model change, not hundreds of generated files.
-
keeps AI where it helps
AI in the loop.
AI in your editor drafts and refines the model through MCP. The compiler handles the rest: grounded, repeatable, reviewable.
Subscription
============
** id : ID
*  owner : Reference@Customer
-  cancelledAt : Date

#blueprint(api-springboot-monorepo)

Cancellation Rules
rule activeOnly
rule notActive
planning.md
Cancellation policy — please review…
Not a planning doc.
discardedchat · prompt
“Generate a subscription service that…”
Not a discarded prompt.
discardedoutput
NestJS · 37 files
generatedarchitecture.png
▦ service → repo → db
Not a stale diagram.
staleoutput
Spring Boot · Java
generatedA model that outlives your code.
- Model what's meaningful.
- Code what's necessary.
- Automate what's repeatable.
Output is real source code you can read, test, and change.
 Meet ModelHike
Own the WHAT. Automate the HOW.
ModelHike is the markdown-like language for application modelling.
You write the Source Model. Blueprints compile it into real, readable code.
38 lines in. 1,418 lines out.
// Built for AI to write, designed for Humans to read.
====
APIs #blueprint(api-springboot-monorepo)
====
+ Flight Module

=== Flight Module ====

Flight
==============
** id : ID
* arrival Station : Reference@Station
- aslot : String
- arrival Status : String
* flight Key : String

getPilotLevel(empId: Int) : String
─────────────────────────────
|> DB Employee · WHERE · FIRST
|> IF years < 5 → "Mid-Level"
|> ELSE → "Senior"
─────────────────────────────

# APIs ["/flight"]
@ apis:: create, delete, list, get-by-id

Station
==============
** id : ID
* code : String
Recorded output · a flight service · api-springboot-monorepo
Recorded output · 37 files · 1,418 lines.
The model stays. The technology can change.
Same model. Different blueprint.
- TypeScript
- REST
- CQRS
- MongoDB
- libs/domain-models/domain.entities.ts
- flight/crud/create.flight.ts
- flight/controller.ts
- flight/module.ts
- flight/requests.http
Template-derived structure — not a recorded generation.
====
APIs #blueprint(api-springboot-monorepo)
====
+ Flight Module
=== Flight Module ====
Flight
==============
** id : ID
* arrival Station : Reference@Station
- aslot : String- Java
- GraphQL
- WebFlux
- MongoDB
- flight/FlightController.java 63
- flight/model/Flight.java 39
- flight/crud/ ×5 commands & queries
- flight/Apis.http 104
- resources/graphql/flightmodule.graphqls
Recorded output · real generated files.
Own your business logic. Not just your codebase.
NestJS and Spring Boot today. More coming soon…
Your spec was a prompt.
Make it a Source Model.
Clone it. Build it. Validate your first model.
- Open source.
- Real code.
- No code cage.